From an Inspection Spreadsheet to a Field-Ready Packet, Without a Backend
A field-services workflow that started with spreadsheet rows and a paper-oriented form became one browser workspace for import, mapping, review, annotation, and export. The public release keeps the architecture visible while removing populated client inputs, branded reference forms, and deployment configuration.
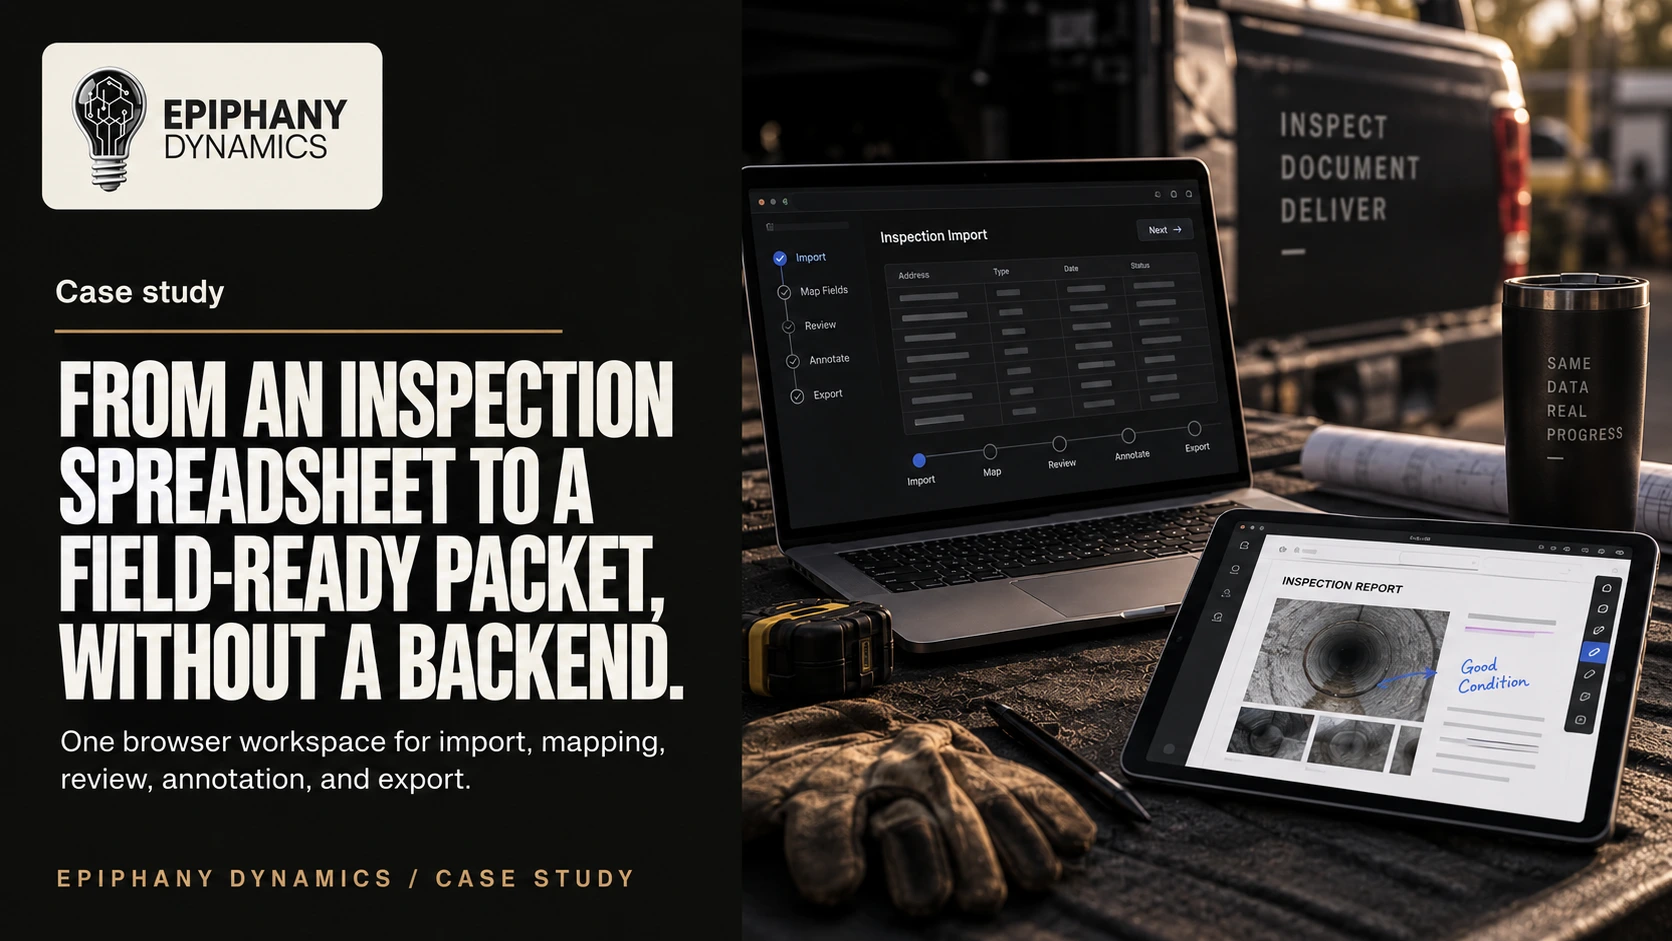
One browser workspace for import, mapping, review, annotation, and export.
The starting point was a familiar field-operations problem: information lived in a spreadsheet, the operator needed to find the right segment, and the final prep sheet had to be rebuilt in a separate paper-oriented format. That creates friction at every handoff and makes a small correction expensive.
The useful product boundary was not another spreadsheet template. It was a reviewable path from messy source rows to a deterministic field packet.
The app imports XLSX, XLS, or CSV files, detects the header row, and proposes mappings into a typed project model. Operators can correct the mapping, edit segment details, add notes and annotations, then export one PDF, a combined PDF, or a ZIP of individual packets.
Dexie keeps the working project in browser-local IndexedDB. There is no account system, server-side upload endpoint, or monthly platform dependency in the public example.
-
01 Input adapters
Spreadsheet parsing and header detection turn inconsistent source layouts into a known shape.
-
02 Human review
Column mapping, segment editing, and annotations keep the operator in control before export.
-
03 Deterministic output
The same typed segment model drives the PDF, batch, and ZIP export paths.
-
04 Privacy boundary
Local persistence avoids creating a new cloud copy of operational documents just to format them.
- 01 One visible review step replaces hidden spreadsheet-to-form copying.
- 02 Operators can correct mappings before a packet is generated.
- 03 Single-job and batch exports share the same output path.
- 04 The architecture leaves a clean seam for OCR without coupling OCR to the field editor or PDF renderer.
The example is sanitized on purpose
The public repository removes populated inspection spreadsheets, client-branded PDFs, client logo assets, deployment identifiers, and internal project instructions. It includes synthetic CSV data so the workflow can be tested without exposing operational records.
The shipped example is a spreadsheet extraction workflow, not an OCR product. That distinction matters. OCR is an input adapter for scanned or image-based documents; it should feed the same typed model, review surface, and export pipeline rather than become the whole application.
That is the broader pattern this build demonstrates: extract into a stable model, give a human a fast correction surface, and keep the final output deterministic. It applies to inspection forms, invoices, intake packets, and other document-heavy operations.
- Does the app send uploaded documents to a server?
- No. The public example is designed as a browser-local workflow with IndexedDB persistence. It has no server-side upload path, login, or external data store.
- What does the extraction layer do?
- It reads spreadsheet rows, detects the header row, maps source columns into a typed segment model, and lets the operator review the mapping before export.
- Does this version include OCR?
- No. The shipped example handles spreadsheets and browser-side PDF generation. OCR is the next input adapter for scanned or image-based documents, while the typed mapping and export layers stay reusable.
Have a document workflow stuck between spreadsheets and PDFs?
Show us the manual loop. We will map the smallest useful system around it.
Free 30-minute audit. No obligation, no pitch. Or take the 2-minute AI quiz.